On-demand compute
Short-term GPU access for experiments, model evaluation, rendering or a fixed project; you run your own software.
Rent GPUs for a project, reserve capacity for ongoing work, or host a private AI model in the UK or on your premises. For businesses and research teams.
Run your own software on rented GPUs, or ask us to scope a managed deployment.
Short-term GPU access for experiments, model evaluation, rendering or a fixed project; you run your own software.
An agreed single- or multi-GPU allocation, on a defined term, for recurring jobs or a service.
A private model hosted for you in the UK or run on your premises, from model and hardware choice to deployment, with application integration if you need it.
Typical work: research runs and parameter sweeps, simulation and engineering solvers, LLM serving and supported adapter fine-tuning, internal assistants and document search, training your own computer vision models, and rendering or batch processing.
Prefer to manage your own instance? Our NVIDIA GB10 and RTX PRO 6000 systems are also rented through Vast.ai, at marketplace prices, availability and terms.
Choose around the workload: the model you need to serve, the number of simultaneous requests, or the solver you need to run.
LLM hosting, a development environment or a single-GPU job.
Best for LLM hosting, development, model evaluation, supported adapter fine-tuning, computer vision training and GPU rendering.
Discuss a single-GPU setupMore independent work, or a model distributed across GPUs.
Best for serving more simultaneous requests (one model copy per GPU), splitting a larger model or training run across GPUs where the software supports it, and running separate experiments, simulations or render jobs side by side.
Discuss a multi-GPU setupMemory-heavy inference and supported scientific workloads.
Best for memory-heavy LLM serving and double-precision (FP64) scientific and simulation software.
Discuss H200 capacityGPU memory is not a model-size guarantee: the model, its active conversations and the software all need room, and separate GPUs do not pool memory automatically. Test your model or software on the chosen configuration before booking; for H200, confirm the variant, GPU count, interconnect and application support.
These are configuration options, not a live availability list; CPU, system memory, storage and networking are sized alongside the GPUs. Manufacturer specifications: RTX PRO 6000 / H200.
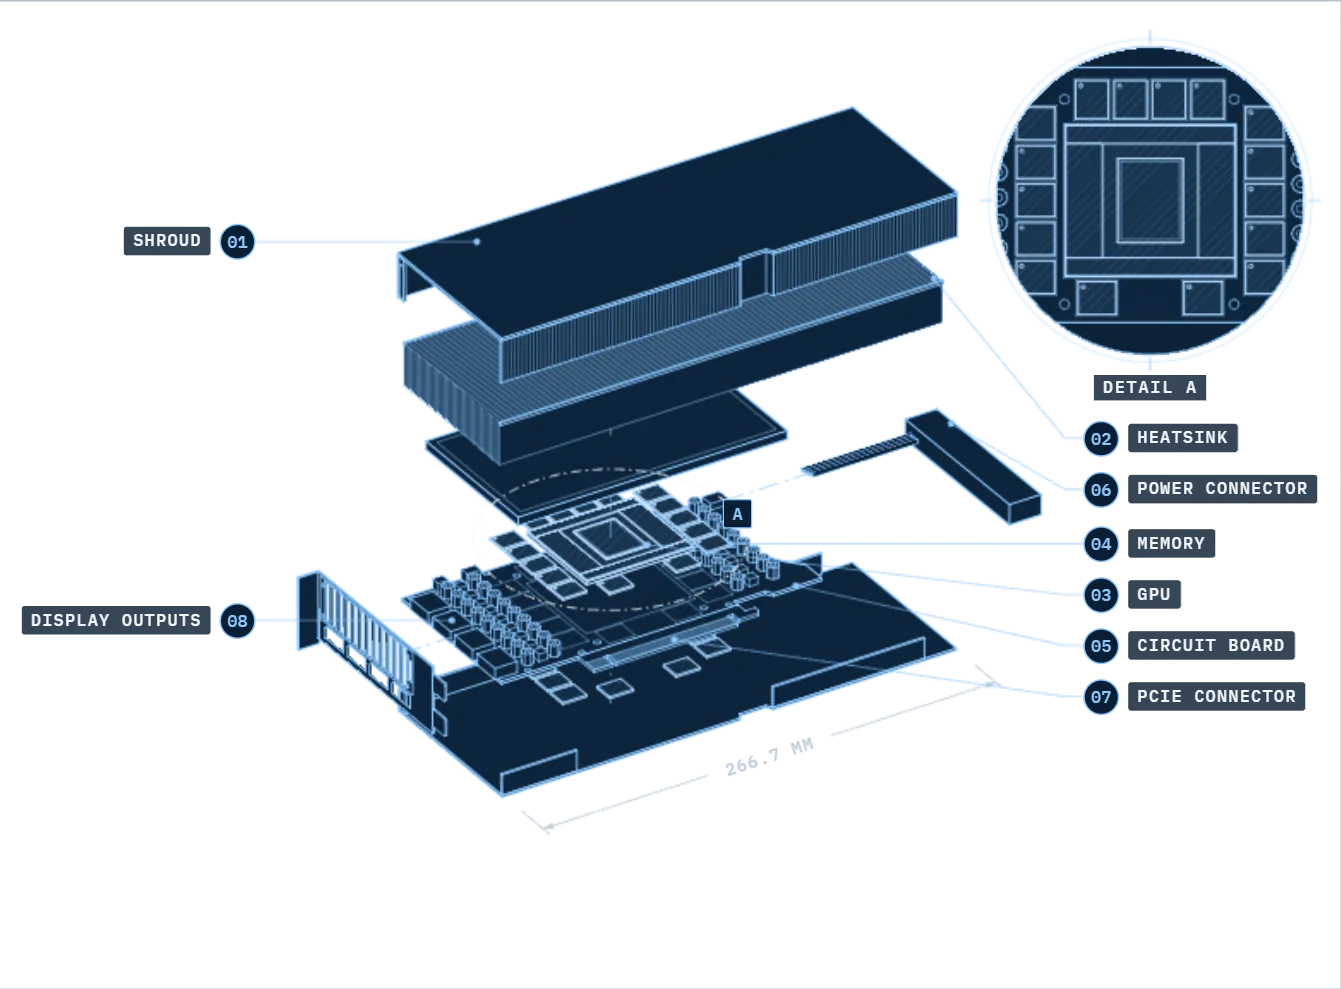
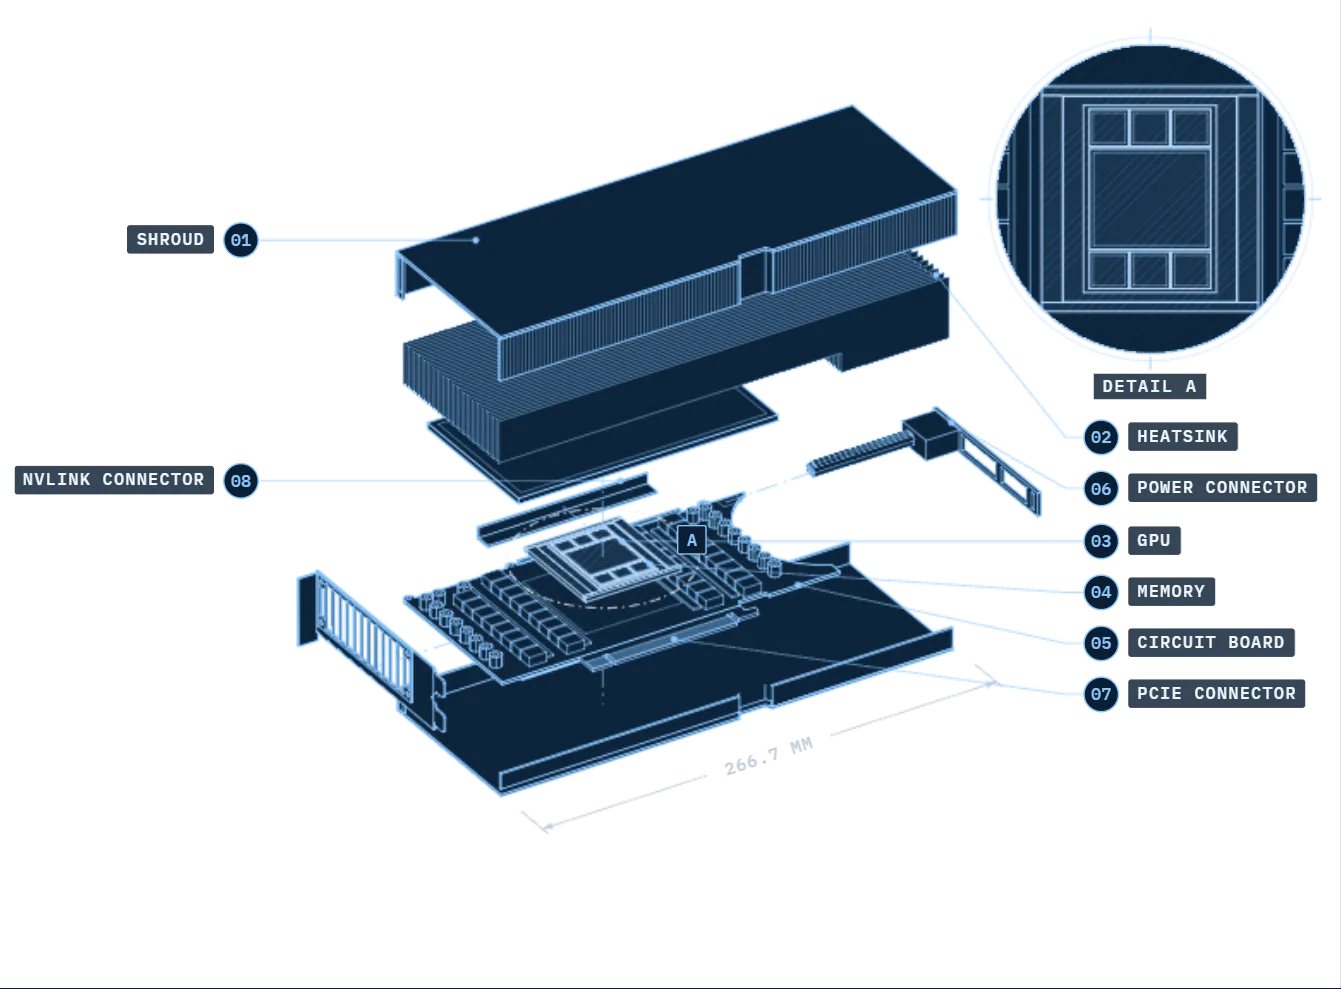
Use a server with the forced airflow required for this passive card.
Board power is configurable up to 600 W; the supported setting depends on the board, firmware, cabling and host system.
Allow additional installation space for cabling and airflow.
Passive cooling means server-provided airflow.
TDP applies to the GPU alone.
Check auxiliary power cabling with the server manufacturer; GPU TDP is configurable up to 600 W within supported platform limits.
Each GPU has its own memory; applications must support distributing work across cards to use them together.
Open-weight models for chat, code, documents and search, hosted for you on UK GPUs or run on your premises, for businesses that do not want confidential prompts or documents routinely sent to a public AI service.
A model loading successfully is not the same as serving it well under load. Longer conversations and more simultaneous requests change the memory budget and response time.
Models change quickly. We help you choose from the latest options for your tasks, data, privacy needs and budget; a smaller model may need less hardware.
Before deployment we agree the model, version, licence and limits on conversation length and simultaneous requests, then test answer quality and response speed (time to first token and output speed) on the chosen hardware.
Internal chat, summarisation and analysis.
Code generation, explanation and repair.
Reading text, tables and charts in document images.
Semantic search: find and rank the documents most relevant to a question, alongside a language model.
We compare vLLM and SGLang on your model, GPU and request pattern rather than assume one is faster.
| UK hosted | Your premises | |
|---|---|---|
| Where the model runs | UK data centre. No server room needed: a selected model runs on compute allocated to you. | Your on-site system. A local model can process prompts and documents within your premises. |
| Where your data goes | Agreed secure connection. The AI model, GPU compute and approved business data sit inside a data boundary. | Local network. External tools, updates and remote support need separate consideration. |
| Who is responsible | Define the data boundary. We agree access, tenant isolation, storage, logging, backups, administrator permissions and which documents an assistant can retrieve before confidential information moves. | Plan the physical setup. We scope hardware, power, cooling, networking and handover with you; installation and ongoing management are agreed separately. |
A private model alone does not guarantee confidentiality or regulatory compliance. | ||
We already host customer workloads through Vast.ai and are bringing company-owned GPU servers into a UK data centre; you deal directly with Percepta about the hardware, deployment and support you need.
For research budgets and business projects, the useful number is the cost of getting the work done. We scope the resources and term before you commit.
GPU model and count, CPU allocation and system memory.
Working storage, retention, backups and any transfer costs.
The duration of on-demand compute, or the term of reserved capacity.
Self-managed compute, deployment assistance or an agreed managed scope; support and maintenance are agreed up front.
Have an existing cloud estimate? Send it with your workload and we will compare equivalent resources; any saving depends on utilisation, software, support and data transfer.
Yes. Discuss short-term access with us, or rent one of our NVIDIA GB10 or RTX PRO 6000 systems through Vast.ai. Direct bookings are quoted and confirmed before the allocation starts; availability and minimum terms depend on the configuration. Capacity, maintenance windows, response times and any service level are set in your contract.
Only if the software can use the GPU effectively. We need the application and version, GPU support, licence conditions, precision requirements and a representative workload. Some simulations are CPU-bound or require a different class of accelerator. We can discuss a representative trial before you commit to a longer allocation.
No. A local model changes where inference runs, but access permissions, administrator access, logs, external tools, backups and support still matter. We confirm the hosting location and data handling for your deployment, including storage, backups and any external services, and agree the deployment boundary with you; hosted and on-premises options have different responsibilities.
We can scope a local AI workstation or server around your use case. Hardware, software licensing, installation, network integration, training and ongoing support are confirmed separately in the proposal.
Do not assume they are included in a GPU rental. Bring details of any commercial software or restricted datasets. Before the work starts, we confirm permitted use, customer responsibilities, any additional storage, backup or support services, and who manages the operating system, models, updates, backups and monitoring. Application work such as integration, document preparation, search indexing and permissions, and ongoing management, is scoped separately from GPU rental.